Making a Zappa Video on My Home GPU with Grok Bot
August 28, 2026 • 👁️ Loading...
I wanted local video generation on the house GPU. Not a cloud demo, not a rented A100. Roux, the Linux box that already sits in the closet running DNS and cameras, has an RTX 4090. I pointed Grok Bot at it and asked it to set the whole thing up.
Two hours later I had a two-minute cut of Don't Eat The Yellow Snow, generated on that card, synced to an MP3 I own, sitting unlisted on my YouTube.
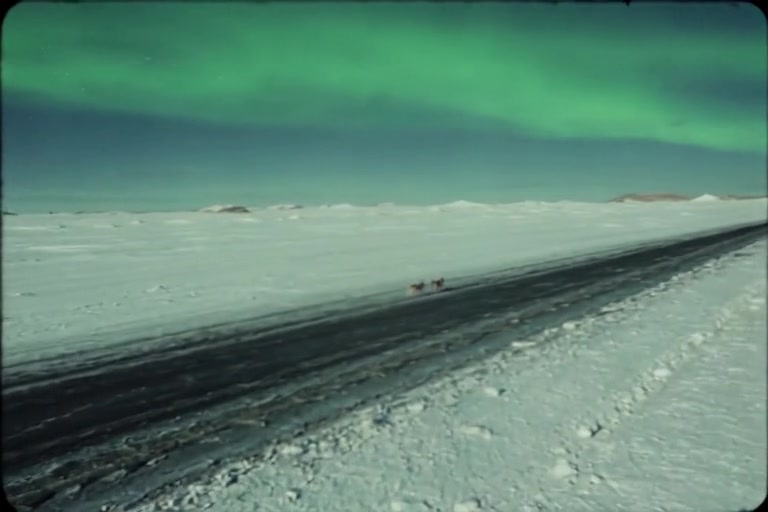
The machine I wasn't allowed to break
Roux is not a lab box. It is the house: DNS, Samba, NFS, Frigate cameras. The brief to Grok Bot was simple. User-space only. No reboot. No apt. No firewall edits. Don't kill Frigate's ffmpeg processes, which already sit on the GPU doing camera decode.
I thought the card was a 3090. It is a 4090. Same 24 GB class, which matters, because the model we wanted does not actually fit in 24 GB unless you get picky about the files.
LTX-2.5, INT8, no cloud
LTX-2.5 from Lightricks had just dropped with day-0 ComfyUI support. Roux already had ComfyUI 0.33.0. The 22B bf16 transformer is a non-starter on this card, so Grok Bot downloaded the official INT8 distilled ComfyUI checkpoint and the lighter conv video VAE onto the backup drive, not the root disk.
Gemma 4 12B runs only as the local text encoder. It gets RAM-swapped so it can share the 24 GB with the video model. Prompt enhancement stayed off. No cloud APIs in the generate path. Ollama Cloud is around for cheap prompt rewriting. We didn't use it for this cut. The prompts were written by hand.
ComfyUI listens on the LAN. Grok Bot talks to it over HTTP, the same /prompt endpoint you'd hit from the UI, except nobody is clicking Queue.
The song, without the lyrics in the prompt
I own the Apostrophe' recording. Grok Bot dropped the MP3 into ~/code/snow, aligned it with Whisper on the 4090, and cut it into 18 shots of about five to eight seconds. Visual prompts only. No lyrics in the graph. 768x512, 24 fps, eight-step distilled schedule. Frame counts are 1 plus a multiple of 8 because that's what LTX wants.
Shot 18 was the test: huskies around a stained patch of yellow snow. Picture and sync were good enough, so we ran the other 17. Grok Bot queued them one at a time (the card peaked at 23.3 of 24.6 GB). That batch ran from 2:39 to 3:01 PM Atlantic, about 22 minutes. Fast shots finished in 15-25 seconds. The slow ones took two and a half to three minutes while ComfyUI reshuffled VRAM. Temperature hit 66C at 100% util. Frigate stayed up. The cameras hitch a little when the 4090 fills. That's the deal.
Then ffmpeg concatenated the clips and muxed the original MP3. Not the model's audio. The file is 16.5 MB and 2:05 long.
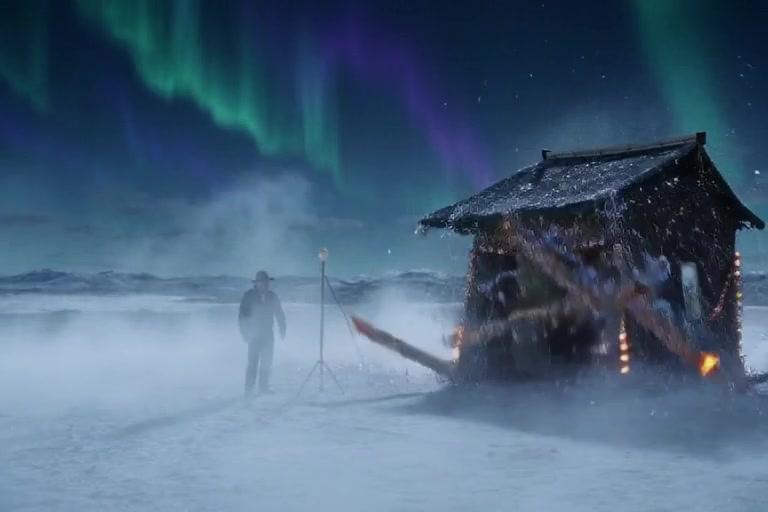
What Grok Bot actually did
I did not sit in ComfyUI. The bot SSHed to Roux, patched a broken kornia import in the LTX custom nodes so the graph would load, wrote a Yellow Snow workflow instead of the anime-fox demo template, pointed the loaders at the INT8 files, queued every shot, watched nvidia-smi, stitched, muxed, then uploaded the cut unlisted to my YouTube and dropped the mp4 in Drive.
The unlisted video is here:
Don't Eat The Yellow Snow (local LTX-2.5 test)
YouTube's Content ID caught the audio, which is fair. It didn't block an unlisted publish. Earnings would be a different story. I'm not monetizing this.
It's not a movie
768x512 looks like a 1970s TV transfer, which accidentally fits. LTX also drifts. The prompt for the last huskies shot produced this instead:
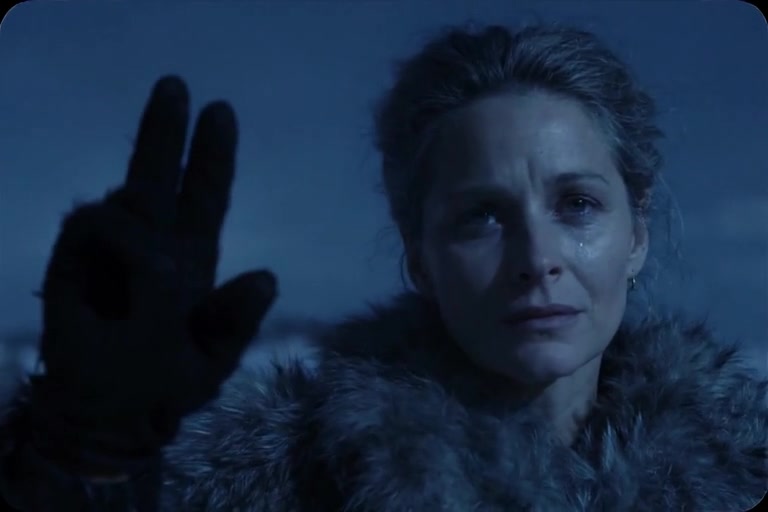
That's the model, not the prompt writer being clever. Fine for a first test. Not fine if you need a locked character.
The rest of the suite, still text-to-video
Same graph, same 4090, four more Apostrophe' tracks. Whisper cut each MP3 into shots, LTX filled an empty latent from a visual prompt, ffmpeg muxed the owned recording.
Father O'Blivion and the first St. Alfonzo's Pancake Breakfast went up unlisted that way. Nanook Rubs It did too, and it is the one that shows the drift problem hardest: faces won't stay put, the trapper turns into someone else, the igloo forgets it is an igloo. Cosmik Debris got muxed on disk and never uploaded. Text-to-video is fast. It is not a music video if you care who is in the frame.
Workflow: text-to-video
This is the Comfy graph behind Yellow Snow and that first suite. Stock LTX-2.5 distilled nodes, not a Civitai pack. The only real tweaks were INT8 weights so the 22B transformer fits in 24 GB, Gemma 4 12B as the local text encoder, prompt enhance off, and a broken kornia import patched so the graph would load.
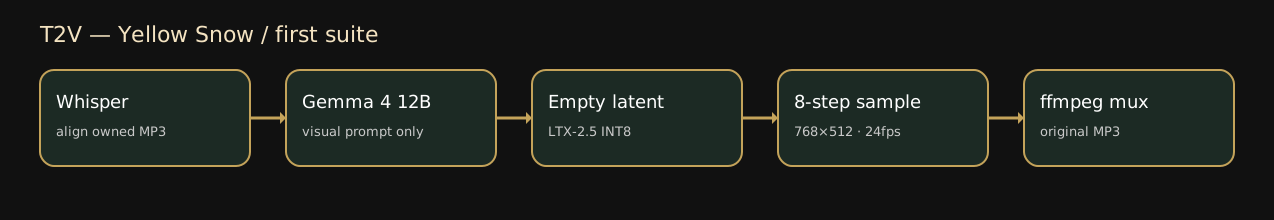
flowchart LR
  A[Whisper on owned MP3] --> B[CLIPTextEncode / Gemma 4 12B]
  B --> C[LTXVConditioning]
  C --> D[EmptyLTXVLatentVideo]
  D --> E[SamplerCustomAdvanced<br/>8-step distilled]
  E --> F[VAEDecode + CreateVideo]
  F --> G[ffmpeg concat + mux original MP3]
Node chain in the API graph: UNETLoader → CLIPLoader (Gemma) → video and audio VAELoader → CLIPTextEncode ×2 → LTXVConditioning → EmptyLTXVLatentVideo → dummy LTXVEmptyLatentAudio → LTXVConcatAVLatent → SamplerCustomAdvanced with ManualSigmas → LTXVSeparateAVLatent → VAEDecodeTiled → CreateVideo → SaveVideo. 768×512, 24 fps, frame count 1 + 8k.
Download the T2V API graph (JSON)
Then we switched to image-to-video
The fix for drift is boring: generate a still you like, then ask LTX to move it. Same graph. Swap EmptyLTXVLatentVideo for LoadImage plus LTXVImgToVideo. That is img2vid, not first-last-frame. No FLF2V node anywhere.
Stills for the cuts that actually worked were made locally with Flux.1 Schnell fp8 on the same 4090 (4-step euler, cfg 1, CLIP-L + T5-XXL fp8 + ae.safetensors). Cloud image APIs bounce the funnier Zappa prompts. Local Flux does not.
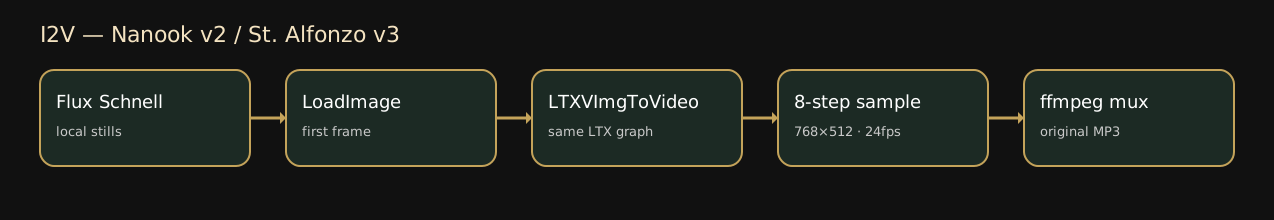
flowchart LR
  A[Flux.1 Schnell still] --> B[LoadImage]
  B --> C[LTXVImgToVideo]
  C --> D[Same LTX-2.5 INT8 sampler]
  D --> E[ffmpeg concat + mux original MP3]
St. Alfonzo v3
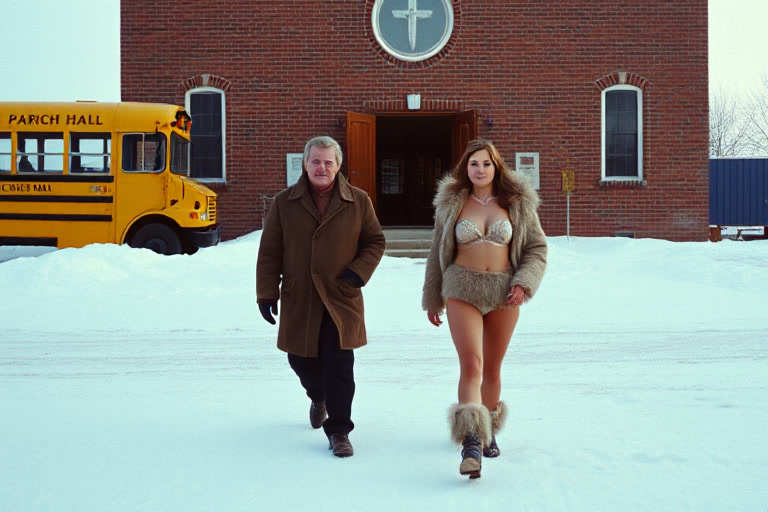
Twenty-two stills, about 1:50, lyric-matched and deliberately un-tame: church kitsch, 1970s bikinis, pancakes that are doing two jobs at once. Each still is a 121-frame LTX I2V clip. Then concat and the original MP3.
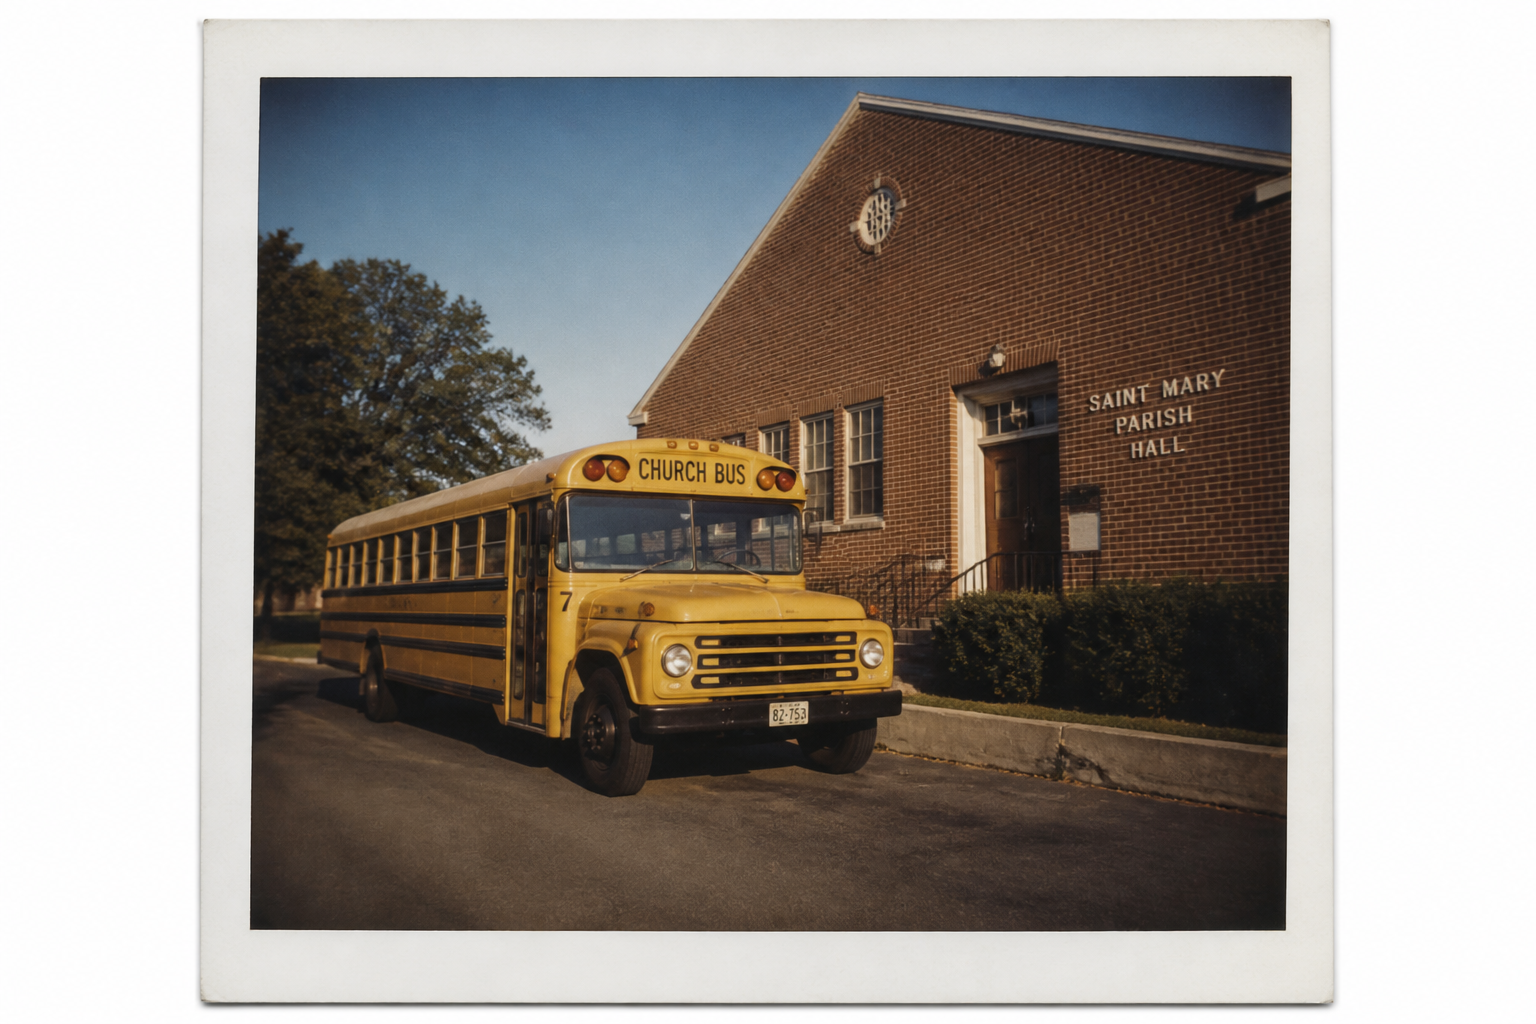
St. Alfonzo's Pancake Breakfast v3
Nanook v2
Forty-two stills, about 4:37. Same I2V runner. Peek-a-boo igloo, yellow snow, a blinded trapper, the long walk to St. Alfonzo's parish. Plus a bikini Eskimo woman because a friend of the song asked for her, and because Nanook without some Zappa sleaze is just a nature documentary.
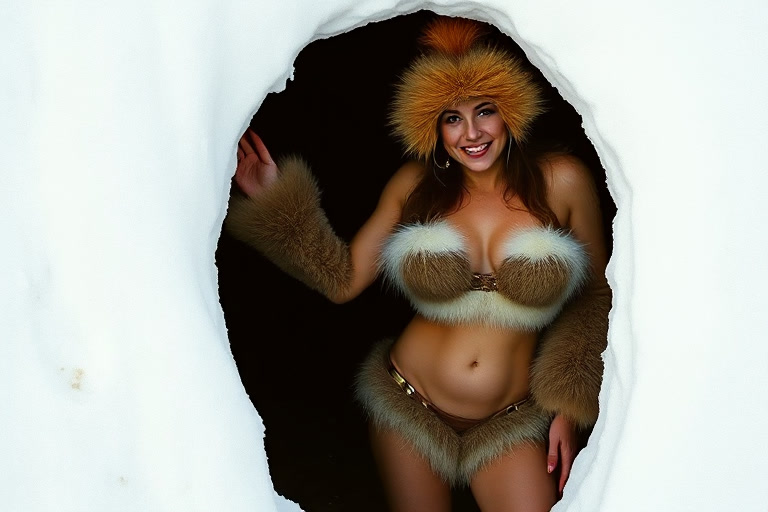
Both, in one file
Nanook first, then Alfonzo. 6:28. Chapters at 0:00 and 4:37. YouTube Content ID found both Zappa tracks. Still not a strike. Unlisted still plays.
Nanook Rubs It / St. Alfonzo's Pancake Breakfast
Weights are gated on Hugging Face. Once they're on disk, generation is free and local. Electricity and a 4090 you already bought.